
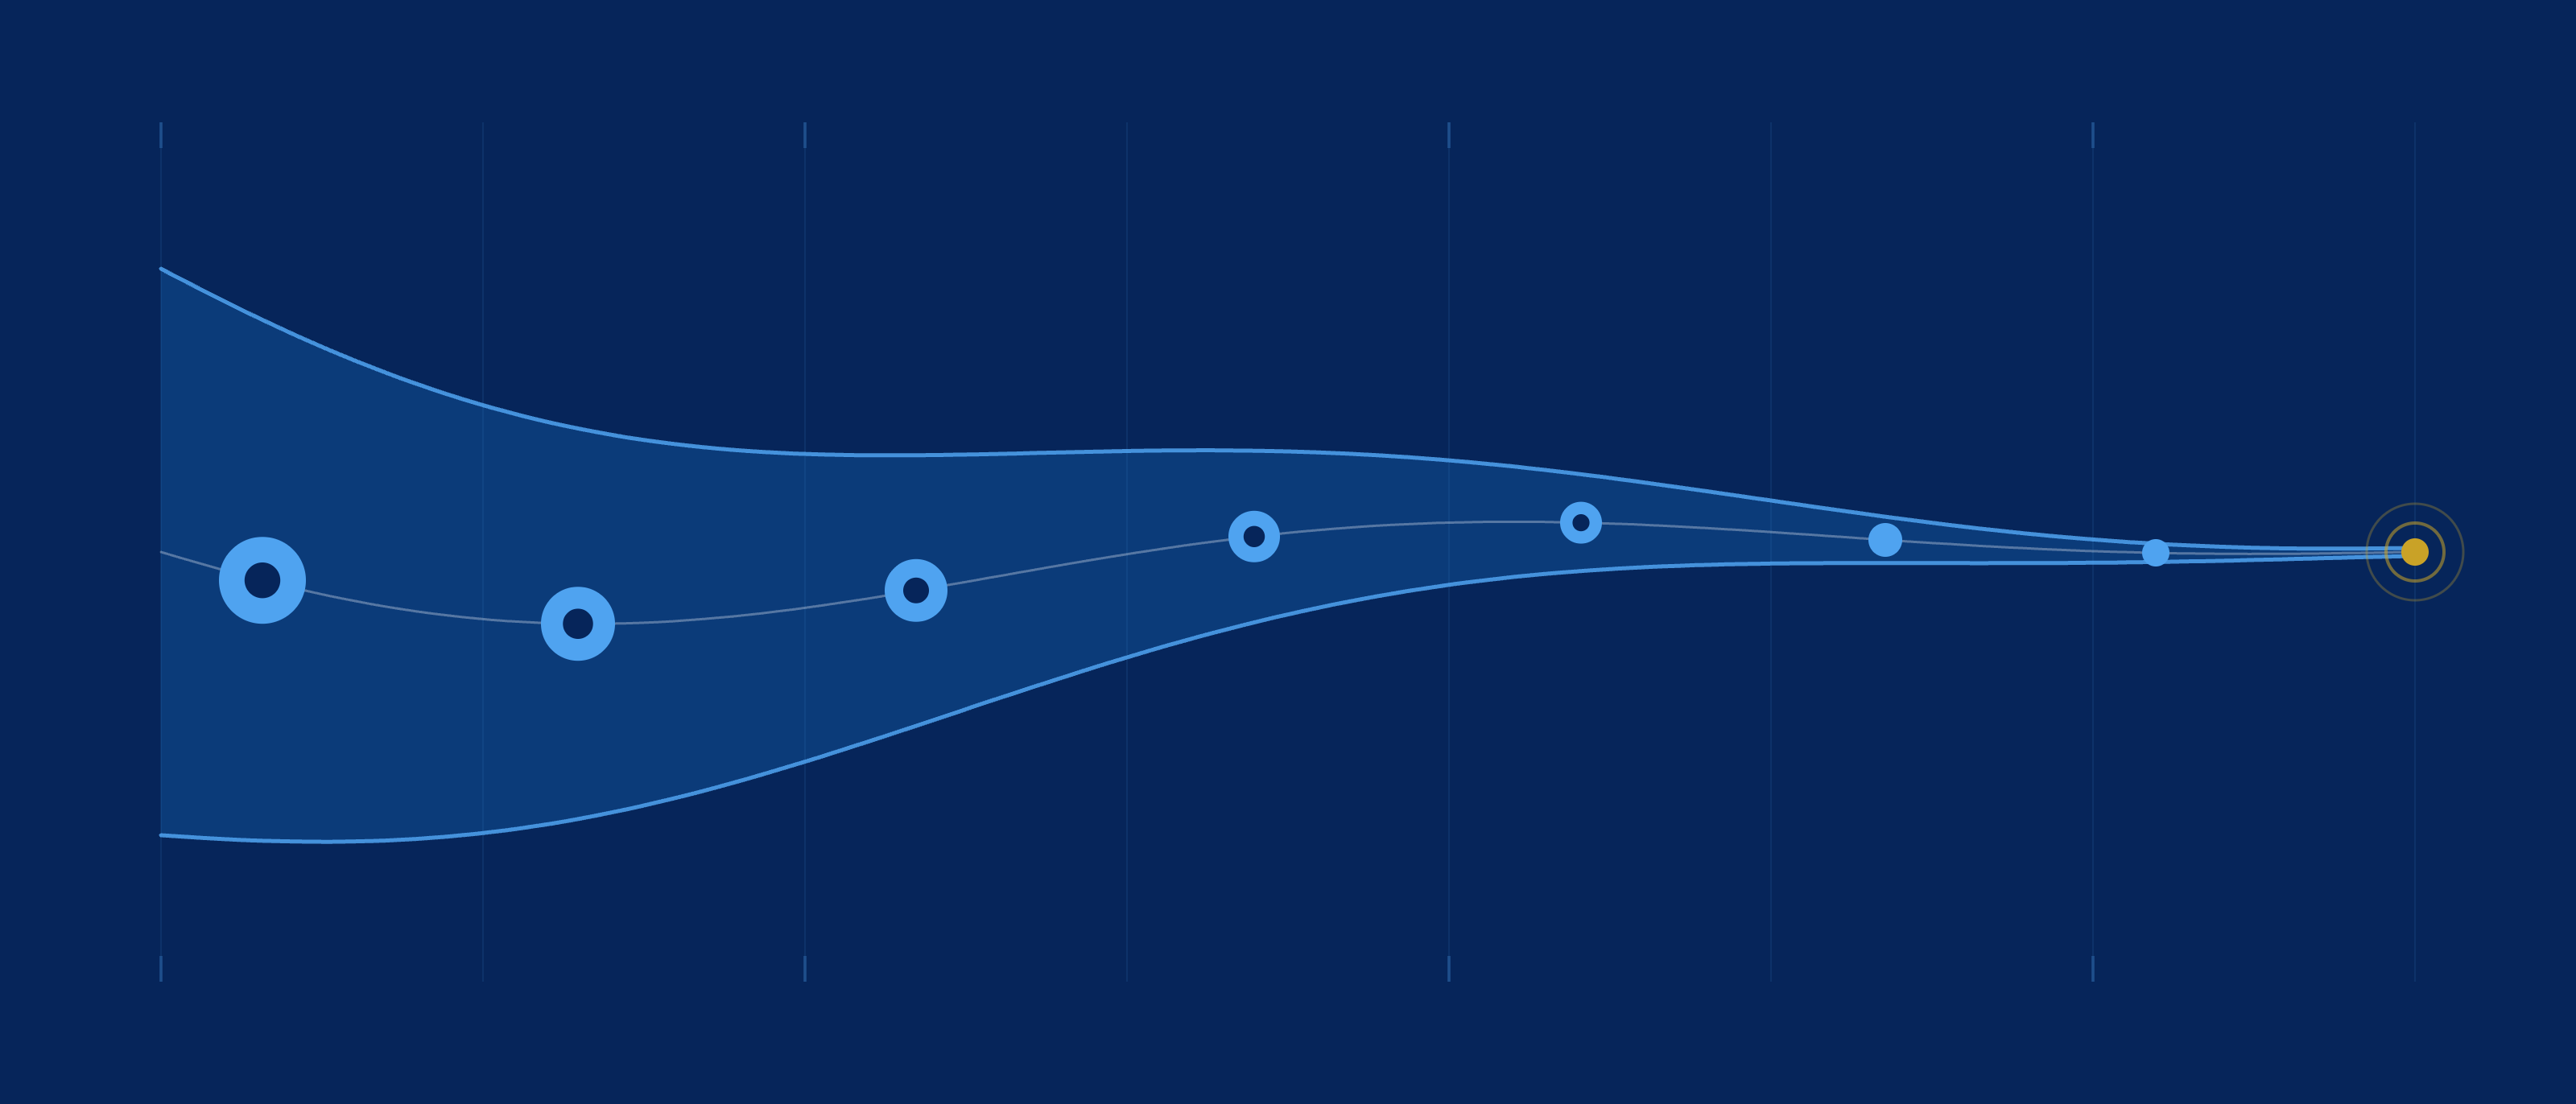
Adaptive Testing: Higher Precision With Fewer Items
A training provider administers a sixty-item placement test to four hundred candidates. The advanced candidate works through twenty foundational items, answering every one correctly, without a single one adding new information about their level. The beginner faces fifteen advanced items and guesses on all of them — which adds nothing either.
Put differently: more than half the test measured nothing at the ends of the distribution. And the cost is not only time but measurement precision itself — because an item that does not differentiate between candidates contributes nothing to locating any of them.
Computerized adaptive testing (CAT) addresses this with an idea that is simple to describe and demanding to implement: do not ask everyone the same items. Ask each candidate the item that is most informative about their level, at this exact moment.
This article explains how it works, the theory it rests on, when it stops, five preconditions without which it fails — and when a fixed-form test remains the better choice.
Key Takeaways
- Adaptive testing does not shorten the test by sacrificing precision. It removes the items that carry no information about the particular candidate.
- It rests on item response theory (IRT), which models the probability of a correct response as a function of candidate ability and item properties.
- It stops when a target precision is reached — a defined standard error — not at a fixed item count.
- An uncalibrated bank means an adaptive test with no foundation. Calibration is a precondition, not a later step.
- CAT is not a universal upgrade: for small cohorts, new banks, and formative assessment, fixed-form testing fits better.
The Problem With Fixed-Form Tests
In a fixed-form test everyone receives the same items. That looks fair, but it distributes precision unevenly:
- At middle ability levels precision is high, because most items were written for that region.
- At the extremes precision falls sharply. The strongest and weakest candidates each receive a less confident estimate, because the few items suited to their level are not enough.
The paradoxical result: the most consequential decisions — who advances to the advanced track, who needs urgent intervention — are made with the least precision.
How Adaptive Testing Works
A four-step loop that repeats after every response:
- Initial estimate. The system starts by assuming the candidate's ability (θ) sits at the mean, or at a prior estimate if one exists.
- Item selection. It selects from the bank the item carrying the most information at the current ability estimate — in practice, the item whose probability of a correct response is closest to the middle.
- Estimate update. After the response, θ is recomputed and the error band around it narrows.
- Stopping check. If the estimate has reached target precision, the test ends; otherwise it returns to step 2.
Step 2 is the key. An item the candidate is 95% likely to answer correctly adds almost nothing — the answer was already known. An item near the midpoint carries the most surprise in its outcome, and therefore the most information.
The Theory: Item Response Theory
Adaptive testing does not function without item response theory (IRT), a framework describing the probability of a correct response in terms of candidate ability and item properties. Items are usually characterized by three parameters:
| Parameter | What it represents | Practical effect |
|---|---|---|
| b — difficulty | The ability level at which the probability of success is midway | Places the item on the ability scale |
| a — discrimination | How sharply the item separates adjacent levels | Higher values mean more information, over a narrower band |
| c — guessing | Probability of answering correctly by chance | High on multiple-choice items; devalues a correct response at low ability |
Models differ in how many parameters they use: a one-parameter model (Rasch) uses difficulty alone, a two-parameter model adds discrimination, and a three-parameter model adds guessing. More parameters make the model more realistic and increase the volume of data needed to estimate them reliably.
The information function is what the engine uses operationally: each item delivers its maximum information at a particular ability level and contributes progressively less further away. The sum of information across administered items determines the standard error of the ability estimate — more information, narrower error.
When Does the Test Stop?
This is where adaptive testing departs fundamentally from fixed-form: there is no predetermined item count.
- Stop at target precision. Continue until the standard error falls below a threshold the institution sets. This rule gives every candidate the same precision at a different item count.
- Stop at a ceiling. A maximum item count or time limit prevents an endless test for a candidate who is difficult to estimate.
- Stop at a decision. In pass/fail testing it is enough to establish that ability lies above or below the cut score with sufficient confidence — without a precise estimate of position.
The third rule is the most efficient in professional licensure, because it spends no items on precision the decision does not require.
It is commonly reported that adaptive testing reaches precision equivalent to a fixed-form test with roughly half the items or fewer — with the ratio varying by bank quality, size, and difficulty spread.
Five Preconditions Without Which It Fails
1. A calibrated bank. Every item needs parameters estimated from real responses, not from an author's difficulty tag. Calibration requires prior administration to a sufficient sample, and the requirement grows with the number of model parameters. An uncalibrated bank makes item selection random with a mathematical veneer.
2. Sufficient bank size. The engine needs multiple alternatives at every difficulty level. A small bank means the same items recycle across similar candidates, which destroys both the security and the measurement benefit.
3. Exposure control. High-information items are the most attractive to the engine, so they get administered to a large share of candidates and leak faster. Exposure control mechanisms therefore constrain how often an item can be used even when it is mathematically optimal — a deliberate trade of some efficiency for security.
4. Content balancing. An engine optimizing for information alone may assemble a test drawn entirely from one topic. It must operate under blueprint constraints: defined proportions per outcome or topic that selection respects regardless of mathematical optimality.
5. A clear review policy. In the conventional design a candidate cannot return to change an earlier answer, because a change invalidates the estimates built on it. This is a genuine constraint on candidate experience and must be disclosed in advance rather than discovered mid-test.
Where It Fits and Where It Does Not
| Context | Fit | Reason |
|---|---|---|
| Placement testing | High | A wide ability range is exactly what CAT handles well |
| Licensure or certification | High | Binary decision; the cut-score stopping rule is highly efficient |
| A university course with a cohort of 60 | Low | Insufficient data to calibrate a course-specific bank |
| Weekly formative assessment | Low | The purpose is diagnostic; coverage matters more than efficiency |
| A new bank with no response history | Not viable | No estimated parameters for the engine to work from |
| Testing tied to specific outcome attainment | Moderate | Possible, under strict content-balancing constraints |
What the Candidate Experiences
A well-tuned adaptive test keeps the probability of a correct response near the midpoint throughout. Which means the strongest and the weakest candidate will both experience the test as hard — because both are facing items right at the edge of their ability.
This produces a recurring misreading: "the questions got harder, so I must be failing." Usually the opposite is true; rising difficulty signals a rising estimate. Which is why explaining in advance how the test works is not communication courtesy but part of the design: anxiety generated by misunderstanding distorts performance and introduces variance unrelated to ability.
What This Requires From the Platform
- An IRT engine that re-estimates ability after every response and selects the next item by information function.
- Storage of item parameters, with periodic recalibration as responses accumulate.
- Configurable stopping rules: target precision, item ceiling, and cut-score rule.
- Exposure control limiting the administration rate of any single item.
- Content-balancing constraints tied to the blueprint and learning outcomes.
- Very low response latency, since the next item is chosen between one click and the next.
- A report giving the assessor the item count administered and the final standard error, not the score alone.
How EvaliX Addresses This
EvaliX supports an item response engine that re-estimates ability after each response and draws the next item to match the current estimate, with stopping rules configurable per assessment.
More importantly, the engine does not operate in isolation from the rest of the platform: item parameters build on the continuous psychometric analysis running across every administration, and item selection remains constrained by outcome alignment — so the engine cannot assemble a test that is mathematically efficient but structurally unbalanced.
And because bank calibration is a precondition, the adoption path we recommend is to run the assessment in fixed form for a term or two while responses accumulate, then switch to adaptive delivery on a calibrated bank.
Request a demo to review your item bank's readiness for adaptive delivery.
FAQs
How many responses does an item need before it is calibrated?
It depends on the model. Simpler models need far smaller samples than models that also estimate discrimination and guessing. The practical rule is to start with a simple model on limited data and move to a more complex one only when response volume justifies it — estimating many parameters from little data produces numbers that look precise and are not stable.
Are scores comparable when candidates receive different items?
Yes, and that is the core benefit of the model. The resulting estimate is not a count of correct answers but a position on a shared ability scale, computed with reference to the difficulty of the items each candidate faced. A candidate who answered twenty items can therefore score higher than one who answered thirty, if their items were harder.
Can adaptive testing be used for an ordinary university course?
Usually not, and the reason is data volume rather than technology. Calibrating a bank specific to a course taught to sixty students a year takes years to accumulate. The better path for a university course is randomized draws from a bank at an equivalent difficulty weight — which delivers variety and security without requiring calibration.